go源码阅读 map
序
关于map的实现,我按照我的思路来看源码,中间尝试了挺多的case,最终选了一些来作为实例
可能跟网上其他人不太一样
准备工作
首先做一些准备工作,跳过一下与编译无关的过程,例如搜索依赖关系
- 样例代码
新建临时目录test_map,在该目录下写入样例代码
// main.go
package main

import (
	"fmt"
)

func test_map() {
	s := make(map[string]int, 3)

	s["chainhelen1"] = 1000
	s["chainhelen2"] = 2000
	s["chainhelen3"] = 3000

	fmt.Printf("chainhelen1 %d\n", s["chainhelen1"])
	fmt.Printf("chainhelen2 %d\n", s["chainhelen2"])
	fmt.Printf("chainhelen3 %d\n", s["chainhelen3"])
}

func main() {
	test_map()
}
-
importcfg
新建文件importcfg,内容如下
# import config
packagefile fmt=/usr/local/go/pkg/linux_amd64/fmt.a
packagefile runtime=/usr/local/go/pkg/linux_amd64/runtime.a
为了最终可以
link成可执行文件,新增文件.linkpackagefile command-line-arguments=$WORK/b001/_pkg_.a packagefile fmt=/usr/local/go/pkg/linux_amd64/fmt.a packagefile runtime=/usr/local/go/pkg/linux_amd64/runtime.a packagefile errors=/usr/local/go/pkg/linux_amd64/errors.a packagefile internal/fmtsort=/usr/local/go/pkg/linux_amd64/internal/fmtsort.a packagefile io=/usr/local/go/pkg/linux_amd64/io.a packagefile math=/usr/local/go/pkg/linux_amd64/math.a packagefile os=/usr/local/go/pkg/linux_amd64/os.a packagefile reflect=/usr/local/go/pkg/linux_amd64/reflect.a packagefile strconv=/usr/local/go/pkg/linux_amd64/strconv.a packagefile sync=/usr/local/go/pkg/linux_amd64/sync.a packagefile unicode/utf8=/usr/local/go/pkg/linux_amd64/unicode/utf8.a packagefile internal/bytealg=/usr/local/go/pkg/linux_amd64/internal/bytealg.a packagefile internal/cpu=/usr/local/go/pkg/linux_amd64/internal/cpu.a packagefile runtime/internal/atomic=/usr/local/go/pkg/linux_amd64/runtime/internal/atomic.a packagefile runtime/internal/math=/usr/local/go/pkg/linux_amd64/runtime/internal/math.a packagefile runtime/internal/sys=/usr/local/go/pkg/linux_amd64/runtime/internal/sys.a packagefile sort=/usr/local/go/pkg/linux_amd64/sort.a packagefile sync/atomic=/usr/local/go/pkg/linux_amd64/sync/atomic.a packagefile math/bits=/usr/local/go/pkg/linux_amd64/math/bits.a packagefile internal/poll=/usr/local/go/pkg/linux_amd64/internal/poll.a packagefile internal/syscall/unix=/usr/local/go/pkg/linux_amd64/internal/syscall/unix.a packagefile internal/testlog=/usr/local/go/pkg/linux_amd64/internal/testlog.a packagefile syscall=/usr/local/go/pkg/linux_amd64/syscall.a packagefile time=/usr/local/go/pkg/linux_amd64/time.a packagefile unicode=/usr/local/go/pkg/linux_amd64/unicode.a packagefile internal/race=/usr/local/go/pkg/linux_amd64/internal/race.a得到这些文件的方式很简单,只需要在go build的时候多加一个 -x 参数,就能知道中间的过程了并且得到中间临时文件的内容
-
ssa.html
这个可以提前生成一下,作为一些辅助信息查看
GOSSAFUNC=test_map /usr/local/go/pkg/tool/linux_amd64/compile -o ./_pkg_.a ./main.go抽象语法树
对于源码来说,编译器前端部分比较关心的是生成抽象语法树是长什么样的
有三种方式:
- 用
goland调试go/src/cmd/compile,配置之前文章有,断点下在lines := parseFiles(flag.Args())之后,查看xtop变量 - 生成ssa.html,就是
/usr/local/go/pkg/tool/linux_amd64/compile-o ./_pkg_.a ./main.go加上GOSSAFUN=test_map - 打印出来抽象语法树,
/usr/local/go/pkg/tool/linux_amd64/compile-o ./_pkg_.a ./main.go的时候加上-W参数
不过2、3方法看到是已经处理过的ast,可以看到源码中
s := make(map[string]int ,3)已经变成了初始化buckets断点方式
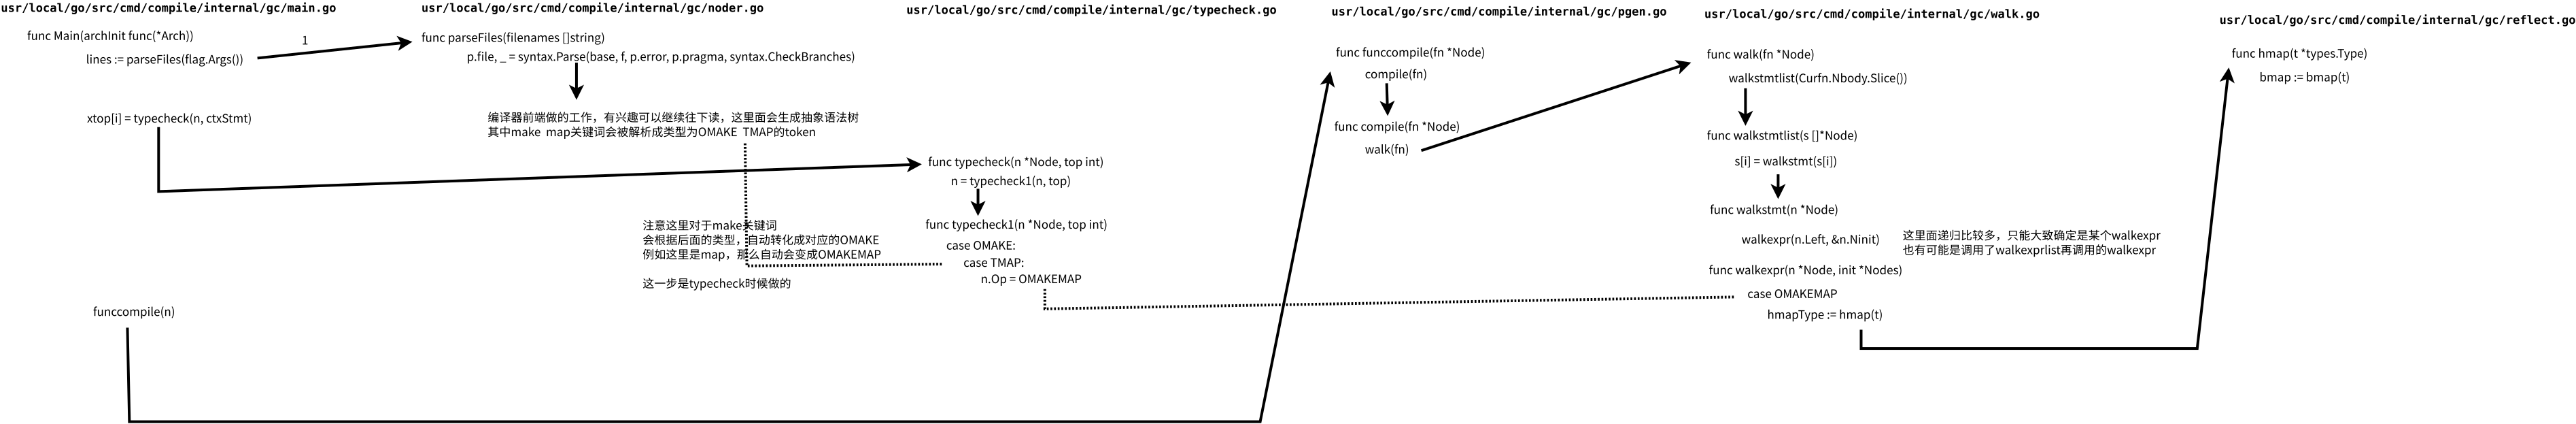
// Phase 3: Type check function bodies.,使用第一种断点方法看一下Phase 3之前的astxtop.Nbody.slice[0].Right.Left 这个节点对应源码中"make"这个关键词 Op 值为 ONONAME(2) Sym.Name 值为 "make"Phase 3之后的ast已经没有了以上节点,对应Node变成了xtop.Nbody.slice[0].Right 这个节点对应源码中"make"这个关键词 Op 值为 OMAKEMAP (72)也就是是说在
类型检查的时候,对于关键词make就会变成对应的类型的操作节点类型make(map) 对应 OMAKEMAP;make(chan) 对应 OMAKECHAN;make([]) 对应 OMAKESLICE
- 用
具体代码流程可以看这

实现
接下来看一下map的实现(具体怎么和运行时关联上的,还没有深入理解)
上图最右下角的地方,显示了hmapType := hmap(t)这个就是编译期间长得样子
// hmap builds a type representing a Hmap structure for the given map type.
// Make sure this stays in sync with runtime/map.go.
func hmap(t *types.Type) *types.Type {
...
	fields := []*types.Field{
		makefield("count", types.Types[TINT]),
		makefield("flags", types.Types[TUINT8]),
		makefield("B", types.Types[TUINT8]),
		makefield("noverflow", types.Types[TUINT16]),
		makefield("hash0", types.Types[TUINT32]), // Used in walk.go for OMAKEMAP.
		makefield("buckets", types.NewPtr(bmap)), // Used in walk.go for OMAKEMAP.
		makefield("oldbuckets", types.NewPtr(bmap)),
		makefield("nevacuate", types.Types[TUINTPTR]),
		makefield("extra", types.Types[TUNSAFEPTR]),
	}
...
}
可以看到编译期间的map结构体类型是动态构造出来的,而且注释上明确写了需要与runtime/map.go同步
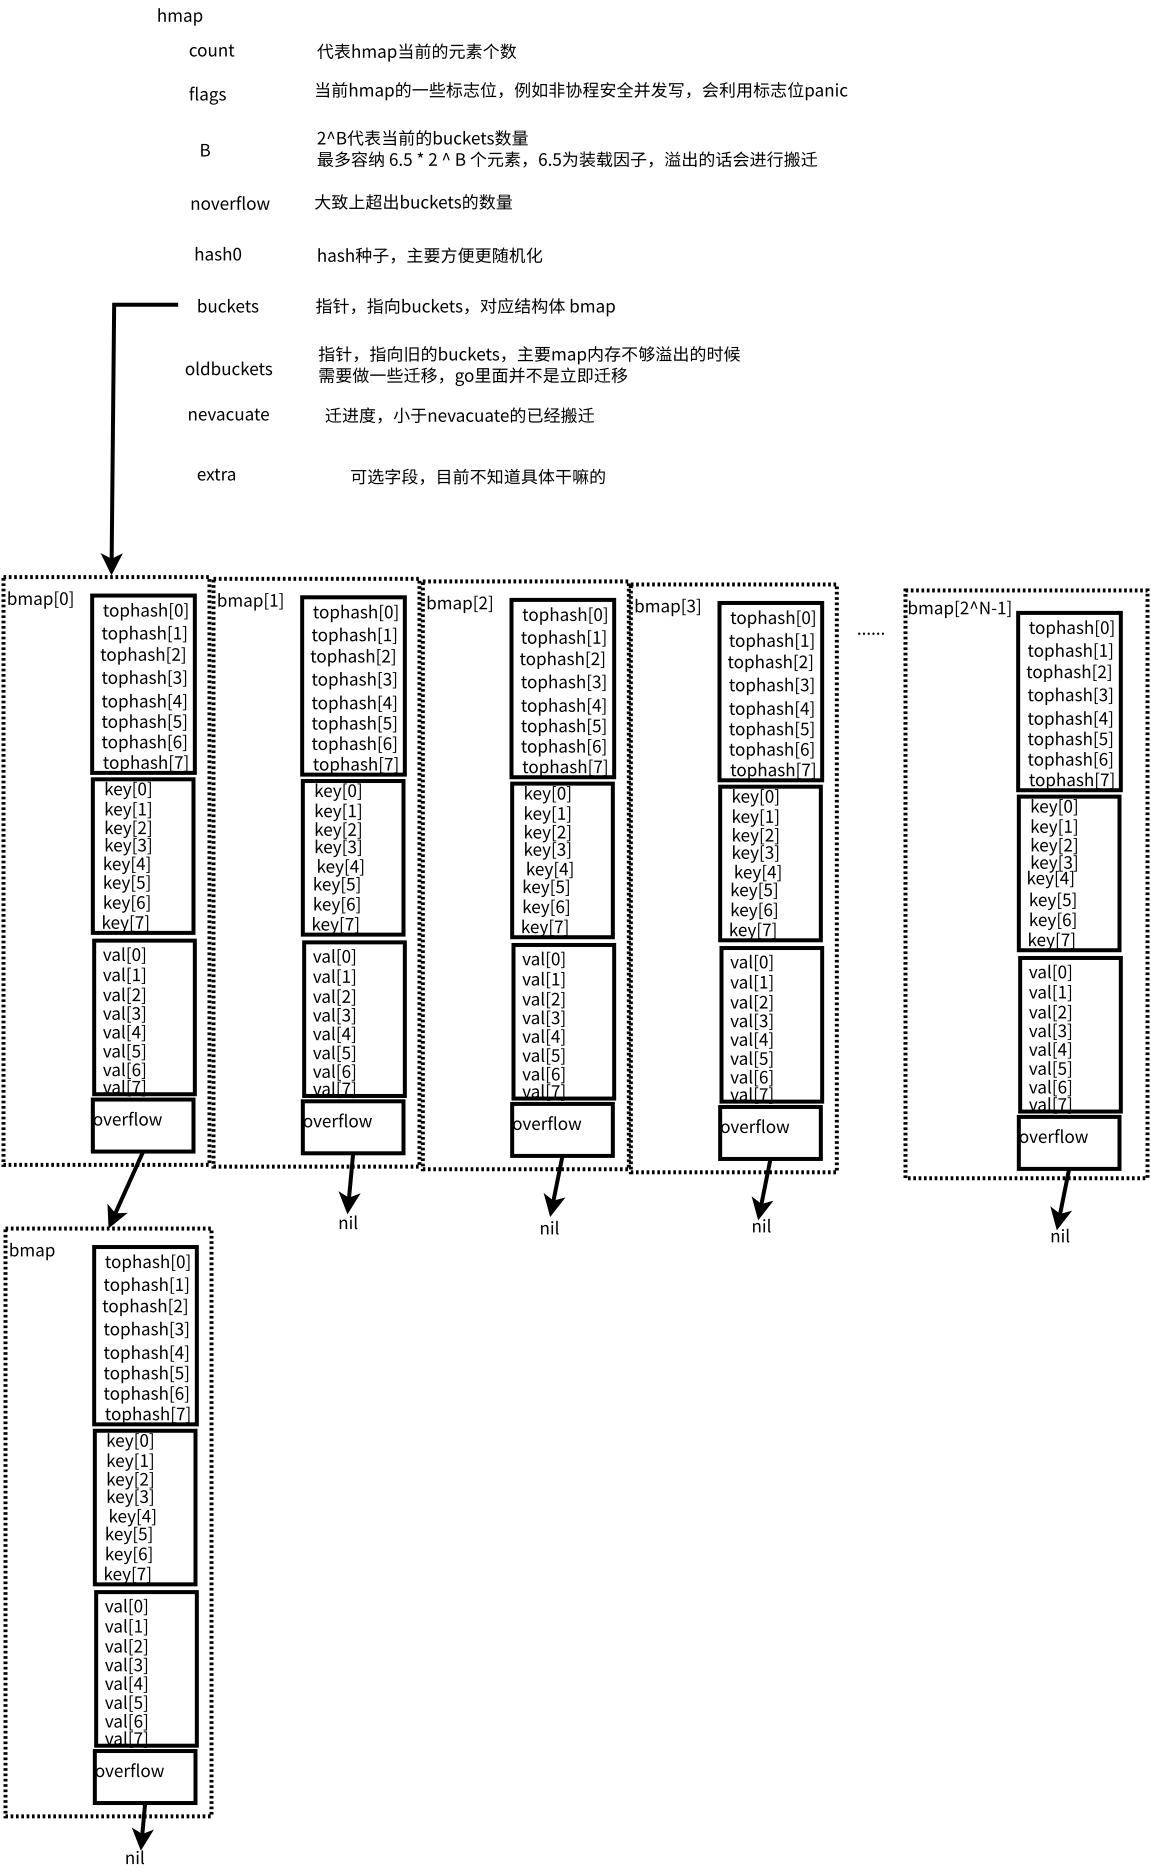
那么具体看一下 runtime/map.go的实现 ,核心结构如下
// A header for a Go map.
type hmap struct {
   count     int    // 等于当前 map 已经存储的元素个数
   flags     uint8  // 标志位,例如如果当前 map 正在写 h.flags&hashWriting == 1
              // 并发写的 panic 也是利用这个标志位查出来的
   B         uint8  // 2^B 代表 buckets 数量
                    // 整个 map最多能容纳 6.5 * 2^B 个元素,13/2=6.5是装载因子
   noverflow uint16 // 大致上溢出的bucket数量,目前我还不清楚保留这个是干嘛的
   hash0     uint32 // hash种子,会让数据的key值更加随机化
   buckets    unsafe.Pointer // 2^B Buckets个数组,当count = 0时该值可能为零
   oldbuckets unsafe.Pointer // 旧buckets的大小,当扩容时候非nil
   nevacuate  uintptr        // 扩容时候的搬迁进度,小于该值的buckets说明数据已经搬迁完成

   extra *mapextra // 可配置的,目前我也不清楚这个是干嘛的
}
上面属性buckets中每一个元素bucket对应如下结构,同样在runtime/map.go文件中
// A bucket for a Go map.
type bmap struct {
	// bucketCnt=1<<3=8,tophash是8个字节大小
	// tophash代表了当前bucket中每个元素key的hash高8位

   // 如果tophash[0] < minTopHash(默认为5,对应有个func tophash代码可知正常一定大于5)
   // 那么tophash[i]就代表了bucket中第i个key的tophash
	tophash [bucketCnt]uint8

	// 紧接着就是8个key,和8个values值,大概长这样
	// [k1][k2]..[k8][v1][v2]...[v8]

	// 再接着就是溢出bmap的指针
}
上面的结构定义不完整,剩余的部分在上面注释中,而实际的在编译过程中,完成的结构代码是在上图bmap := bmap(t) 完成的
func bmap(t *types.Type) *types.Type {
...
	keys := makefield("keys", arr)
...
	values := makefield("values", arr)
...
	overflow := makefield("overflow", otyp)
...
}
大概最终形成在内存中的长得样子
注释
放在最后是因为我做了核心函数的代码细节注释,如果只是想理解大致实现,没有必要看最后的部分
而且源码的注释写得很清楚,大部分我只是做一些简单翻译
初始化
// 正常初始化map的代码,hint是只是make传入的大小(注意这里影响的是bucket数量,而不是容纳元素数量)
// 如果编译器发现当前的map可以直接使用栈内存,那么参数传入的h *hmap就是非空;否则h为nil,函数会将其创建在堆上面
func makemap(t *maptype, hint int, h *hmap) *hmap {
  // 计算用户传入的make大小会使用多大内存,如果太大的,直接将其值置为零
	mem, overflow := math.MulUintptr(uintptr(hint), t.bucket.size)
	if overflow || mem > maxAlloc {
		hint = 0
	}

	// 如果 h *hmap为空就是在栈上;否则在堆上面创建
	if h == nil {
		h = new(hmap)
	}
	// hash种子
	h.hash0 = fastrand()

	// 主要保证 2^B * 6.5 >= hint
	// 2^B代表bucket数量,6.5是装载因子,保证有足够多的容量可以容纳所有容量
	B := uint8(0)
	for overLoadFactor(hint, B) {
		B++
	}
	h.B = B

	// allocate initial hash table
	// if B == 0, the buckets field is allocated lazily later (in mapassign)
	// If hint is large zeroing this memory could take a while.

	// 如果 B == 0,buckets的内存懒分配,等到mapassign的时候分配
	if h.B != 0 {
		var nextOverflow *bmap
		// buckets 内存分配,nextOverflow 主要是提前分配好准备溢出的buckets
		h.buckets, nextOverflow = makeBucketArray(t, h.B, nil)
		if nextOverflow != nil {
			h.extra = new(mapextra)
			h.extra.nextOverflow = nextOverflow
		}
	}
	return h
}
对应上面代码分配内存的地方makeBucketArray
// dirtyalloc 是为了可以内存复用,对于上面的makemap来看,其实并没有复用
func makeBucketArray(t *maptype, b uint8, dirtyalloc unsafe.Pointer) (buckets unsafe.Pointer, nextOverflow *bmap) {
	if b >= 4 {
	    // 对于make(map)初始值大于 4(即2^4=16个buckets)
	    // 提前额外申请2^(b-4)个buckets作为Overflow
		nbuckets += bucketShift(b - 4)

		// 向上取整,这个主要为了方便内存管理,对齐go中内存的大小
		// 主要代码在 go/src/runtime/sizeclasses.go
		// class  bytes/obj  bytes/span  objects  tail waste  max waste
		//     1          8        8192     1024           0     87.50%
		//     2         16        8192      512           0     43.75%
		//     3         32        8192      256           0     46.88%
		//     4         48        8192      170          32     31.52%
		//     5         64        8192      128           0     23.44%
		//     6         80        8192      102          32     19.07%
		//     7         96        8192       85          32     15.95%
		//     8        112        8192       73          16     13.56%
		//     9        128        8192       64           0     11.72%
		up := roundupsize(sz)
	}

	// 分配内存
		buckets = newarray(t.bucket, int(nbuckets))

	if base != nbuckets {
		// 设置上面多申请的内存作为 overflow
		nextOverflow = (*bmap)(add(buckets, base*uintptr(t.bucketsize)))

		// 这个东西是为了让最后一个bucket的overflow,指向开头的bucket
		// 类似于起始亦结尾,蛇头咬蛇尾
		last := (*bmap)(add(buckets, (nbuckets-1)*uintptr(t.bucketsize)))
		last.setoverflow(t, (*bmap)(buckets))
	}
	return buckets, nextOverflow
}
访问元素
func mapaccess1(t *maptype, h *hmap, key unsafe.Pointer) unsafe.Pointer {
    // 可以参照上面的流程,看到 b,是可能保存该数据的 bucket
    // 第一层遍历b、b后续overflow的bucket,第二层遍历bucket里面的所有的key
bucketloop:
	for ; b != nil; b = b.overflow(t) {
		for i := uintptr(0); i < bucketCnt; i++ {
	    ...
	            // 小对象value一点关系都没有
				if t.indirectvalue() {
					v = *((*unsafe.Pointer)(v))
				}
         ...
	}
}
这里有个很有趣的东西关于indirective(),如果出现value的值width很大,那么实际底层value存储的是指针
当出现map的value width过大,访问数据将不会调用直接调用mapcess1,而是调用mapaccess1_fat
这个 width 边界大小在 cmd/compile/internal/gc/reflect.go 定义的,MAXVALSIZE = 128
arr := [129]int{1}
mp := make(map[string][129]int)
mp["hello"] = arr
b := mp["hello"]
value 在底层被定义成指针代码 refect.go:1292,例如上面代码 访问mp["hello"] 就会调用 mapaccess1_fat
同样的key也有类似优化
这里面有个很容混淆的概念,如果map的value类型是指针,实际不会触发这种机制,因为指针在64位机器就是8字节的无符号整型
赋值
func mapassign(t *maptype, h *hmap, key unsafe.Point) {
    ...
    // 计算hash
    hash := alg.hash(key, uintptr(h.hash0))

    // 类似懒加载,上面初始化讲过
    if h.buckets == nil {
		h.buckets = newobject(t.bucket) // newarray(t.bucket, 1)
	}
    ....

    // 取余数,因为 m % (2^N)等于 m & (2^N - 1)
    // 这个原理是因为2^N的二进制只有第N位是1,2^N-1末尾都是1
    bucket := hash & bucketMask(h.B)

    // 如果可以搬迁,那么进行一步搬迁工作
    if h.growing() {
		growWork(t, h, bucket)
	}

	// 找到对应的bucket插入位置 i,和原来的key,key对应的val(如果存在的话)
	var inserti *uint8
	var insertk unsafe.Pointer
	var val unsafe.Point

	// 都说`tophash`是为了快速是错,不知真假
	top := tophash(hash)
	for {
		for i := uintptr(0); i < bucketCnt; i++ {
			if b.tophash[i] != top {
			...
}
遗留
迭代器
这部分源码挺好读,就是编译进去的问题
迁移
只赋值并且该key不存在的情况下,才可能触发迁移hashGrow
一旦进入正在迁移状态,只有赋值、删除会发生迁移两组bucket迁移(也可能是一组,组就是上图上面的一列bmap);第一组是当前所操作的key所在bucket,第二组是会做顺序bucket迁移(也就是小于nevacuate都说明已经迁移完成的原因)
调试
dlv的调试是进不了runtime的源码中,而gdb是可以的